
AI agent cooperation From the report of
One malicious delegate, replayed incidents and the cost of compaction
- Authors’ claims
Where playtesting bots diverge from humans, cell by cell
Smirnov, Pertoft and Karimi report a stratified testing framework that compares full behavioral distributions of humans and agents within contextual cells and then discovers subgroup rules describing where they diverge. In a production case study on a commercial match-3 game with two playtesting agents, session-level metrics dominated by win and loss outcomes carry little signal beyond mean comparisons, while process-level metrics such as move efficiency expose genuine differences: the agents diverge substantially from humans in some game modes and show no detectable divergence in others. The implementation is released as open source.
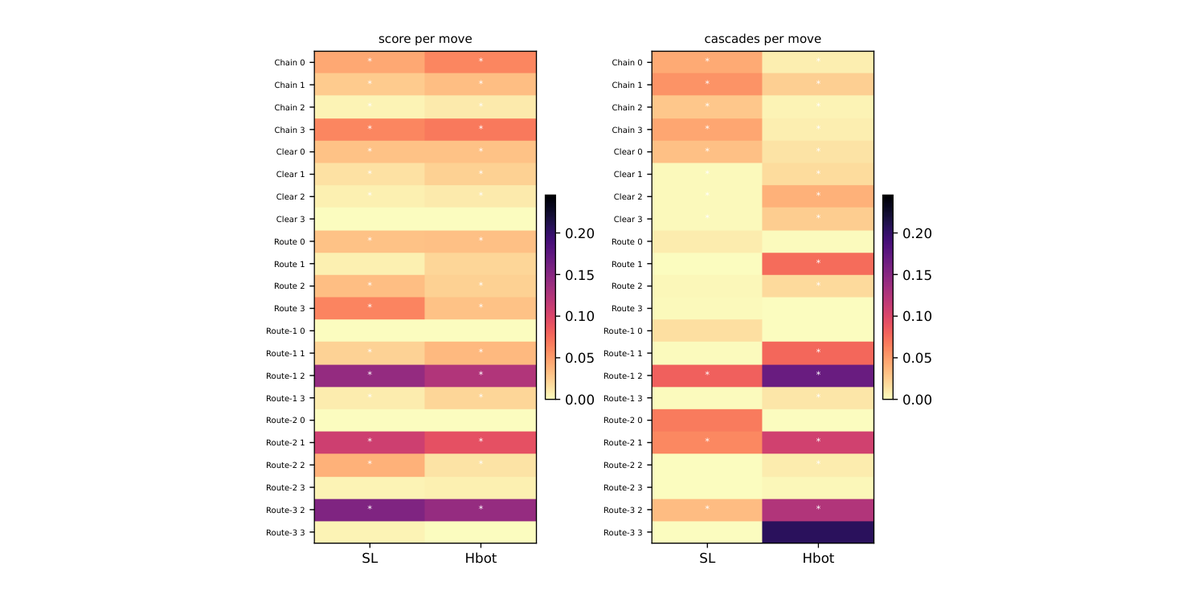
Assessment
Aggregate human-likeness scores certify the average and miss the mode. Cell-level distributional testing makes 'the agent behaves like a human' falsifiable per context, and the same stratification applies anywhere an agent is graded on outcomes alone.
Submitted November 19; appeared in the November 20 listing.